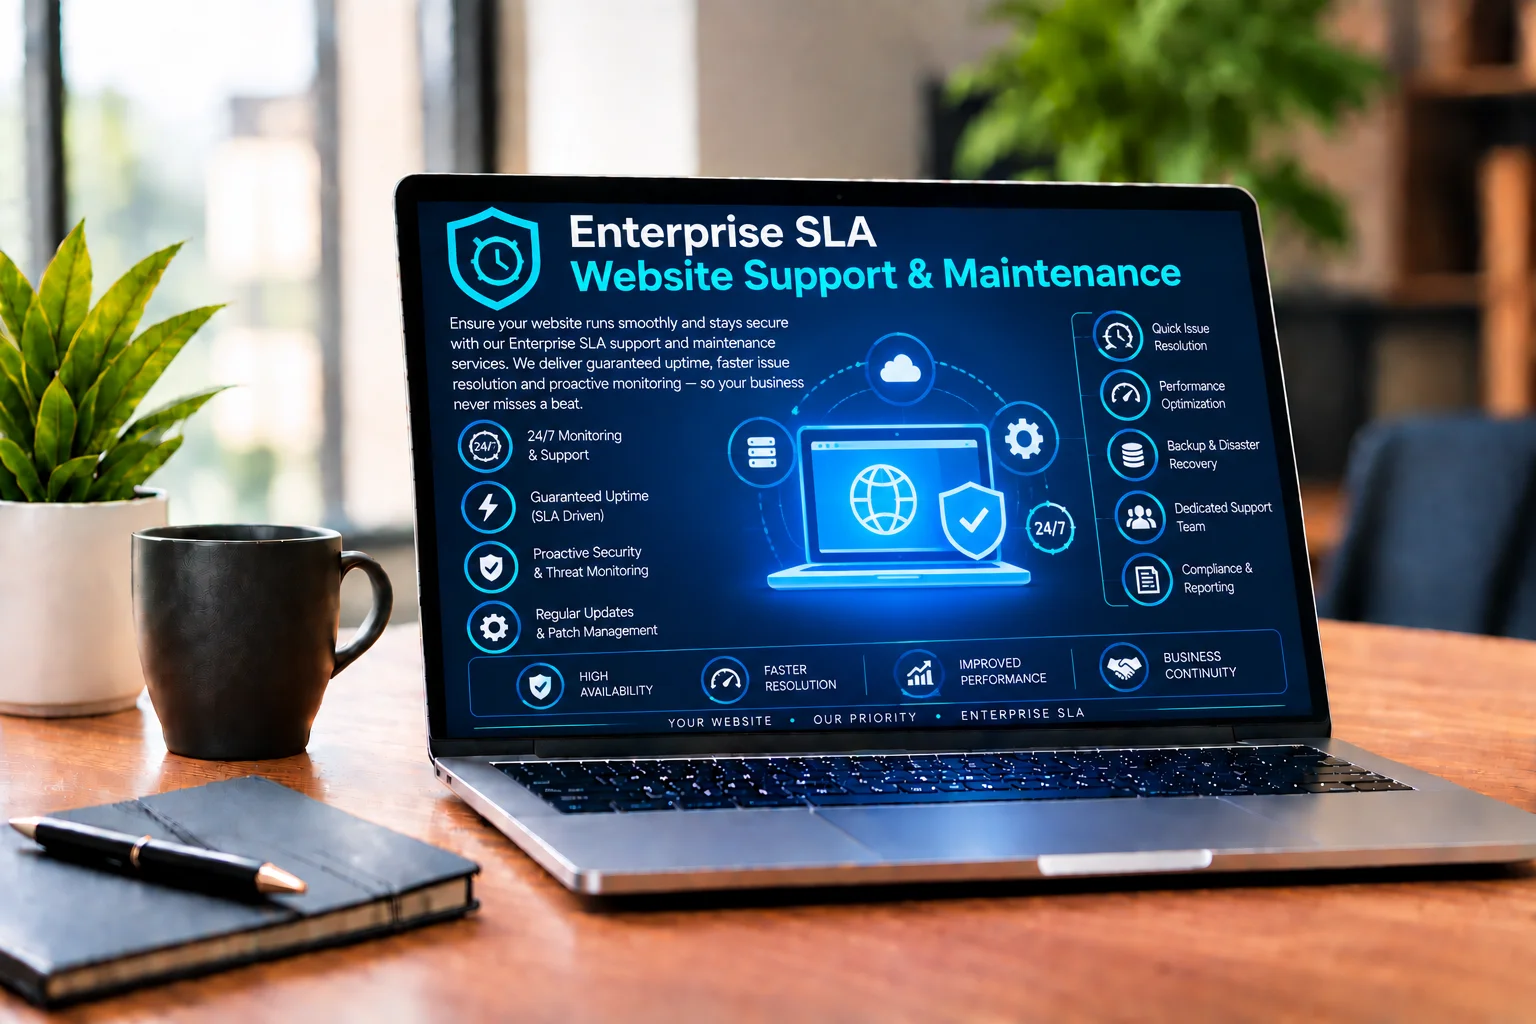
Standard shared support queues cannot meet the demands of mission-critical enterprise systems. We provide dedicated engineering pods, continuous infrastructure monitoring, and rigorous SLA compliance.
Our Enterprise Support tier pairs your internal teams with a dedicated Principal Solutions Architect and Site Reliability Engineers (SRE) who understand your exact architecture, data pipelines, security requirements, and deployment workflows.
From preemptive telemetry monitoring and automatic failover clustering to monthly development sprints and disaster recovery simulations, we guarantee zero operational surprises and peak digital resilience.
See how our proactive enterprise management replaces generic ticketing queues with dedicated high-availability engineering.
Comprehensive technical governance covering incident response, infrastructure scaling, data protection, security audits, and dedicated engineering sprints.
Contractually guaranteed 15-minute triage response for high-severity site outages, broken checkouts, or security incidents 24/7/365.
Continuous transaction log shipping to AWS S3 / Cloudflare R2 allowing granular, second-by-second point-in-time database restoration.
Assigned senior full-stack architect and DevOps engineer with intimate knowledge of your exact codebase, microservices, and server topology.
Proactive quarterly vulnerability scans, simulated ethical hacking assessments, OWASP top-10 threat mitigations, and compliance verification.
Management of multi-node cloud clusters (AWS/GCP), Redis memory caching, automated horizontal scaling, and zero-downtime blue/green deployments.
Pre-allocated block of 30+ senior developer hours every month dedicated to new feature rollouts, API integrations, and heavy code refactoring.
A disciplined, ITIL-aligned governance model ensuring proactive system prevention, rapid incident triage, and continuous performance refinement.
Comprehensive codebase audit, database profiling, server topography mapping, and CI/CD pipeline establishment.
Implementation of New Relic/Datadog telemetry, WAF configuration, and continuous real-time backup replication protocols.
Automated deployment of security patches and core updates strictly tested in staging with visual regression software before pushing live.
Immediate alerts trigger on-call DevOps intervention for traffic spikes or anomalies, resolving issues before end-users notice.
Execution of requested custom feature builds, heavy API integrations, or CRM syncing utilizing reserved monthly development block hours.
Quarterly Business Reviews detailing SLA compliance metrics, security scan outcomes, infrastructure load capacities, and strategic roadmaps.
Delivering strict uptime guarantees, compliance auditing, and custom integrations across demanding enterprise domains.
Everything you need to know about our response SLAs, engineering sprint allocations, escalation protocols, and infrastructure governance.
Schedule a private discovery session with our Principal Solutions Architect to benchmark your uptime requirements, disaster recovery plans, and monthly sprint velocity.